I like the momentmessy data startsmaking sense.
I’m Mahesh, a data analyst in Sydney with a Master of Data Science from Macquarie University and a computer science degree behind it.
I work across the whole data lifecycle rather than one slice of it, and the part I care about most is the unglamorous middle: making a messy dataset trustworthy enough that someone can act on it without checking your working.
Mahesh Sai Kandula
- location
- Sydney, Australia
- education
- MSc Data Science · Macquarie
- foundation
- B.Tech Computer Science
- practice
- Analytics · Engineering · ML
- tooling
- Python · SQL · PostgreSQL · Tableau
- status
- Open to opportunities
6 attributes
How I ended up building data systems.
- 01Where I started
A computer science foundation.
I studied Computer Science & Engineering at GITAM University in India, finishing in 2024 with a CGPA of 8.75 / 10. That degree is why I think about data the way I do: as systems that have to be designed, not spreadsheets that happen to exist.
Writing code came first. Caring about whether the numbers coming out of that code were actually true came shortly after, and that turned out to be the more interesting problem.
- Degree
- B.Tech, Computer Science & Engineering
- Institution
- GITAM University, India
- Years
- 2020 – 2024
- Result
- CGPA 8.75 / 10
- 02Why data
Then Sydney, and the full pipeline.
I moved to Sydney for a Master of Data Science at Macquarie University (2024–2026), where the work stopped being about single models and started being about whole systems: schema design, ingestion, data quality, the SQL layer underneath a dashboard, and only then the modelling.
That is the part I kept gravitating towards. Most of my projects now run the entire length of a pipeline rather than picking one comfortable slice of it.
- Degree
- Master of Data Science
- Institution
- Macquarie University, Sydney
- Years
- 2024 – 2026
- Result
- WAM 75.7
- 03Where I've worked
Two internships, both about data integrity.
At Tech Mahindra (Hyderabad, hybrid, part-time, Jun 2023 – Mar 2024) I consolidated ~30K customer records across 6 source tables (profile, billing, usage, payments, complaints, service interactions) using SQL joins, CTEs, CASE expressions and aggregations. The part that actually mattered was collapsing 5 one-to-many transactional sources to one row per customer without join fan-out, then validating row counts, customer-ID uniqueness and aggregate totals before anyone analysed anything.
On top of that I cleaned the data in Python across 5+ churn dimensions, engineered 8 behavioural features, and compared Logistic Regression, Decision Tree and Random Forest on precision, recall, F1 and ROC-AUC. It fed a Power BI dashboard tracking churn rate, high-risk customers and 4+ customer segments for weekly and monthly retention reporting.
At Total IT Global in Sydney (remote, Dec 2025 – Feb 2026) I owned data integrity for daily operational reporting at 50–70 tickets a day, standardising 3–5 inconsistent Excel extracts into one master dataset at one row per ticket. I built a reconciliation control (previous open + new − resolved = current open) that caught mismatches and duplicate records before figures were reported, and documented the workflow so the rest of the team could repeat it.
- First role
- Analytics Intern, Tech Mahindra · Jun 2023 – Mar 2024
- Second role
- Data & Reporting Intern, Total IT Global · Dec 2025 – Feb 2026
- Records consolidated
- ~30K across 6 source tables
- Daily reporting volume
- 50–70 tickets
- 04How I work
The decisions I keep making.
The through-line in my work is refusing to make the data look better than it is. On PayScope I built a data-quality framework that flags invalid records instead of deleting them, so the audit trail survives and an analyst can see exactly what was wrong. Trusted transaction coverage came out at 69.7%, and that number is honest.
The same instinct shows up everywhere else. I use an aggregate-before-join pattern in SQL marts to stop grain mismatches quietly inflating every downstream metric. On the Airbnb model I deliberately excluded leakage columns that would have let it cheat, and when the price field turned out to be 100% null I changed the feature strategy and documented it rather than quietly dropping the dataset.
And I try to make a result explain itself. SHAP on the Airbnb classifier showed that host portfolio size, not price or amenities, drove guest satisfaction, and it explained away a misleading pattern in the raw data at the same time. Two methods landing on the same answer is worth more to me than one impressive score.
- 05What's next
Where I want to put this.
Alongside the degree I completed the IBM Data Science and Google Data Analytics Professional Certificates and an AWS Cloud Virtual Internship, and I keep building end-to-end projects because that is where the awkward, unglamorous problems live.
I'm currently looking for a data analyst role in Sydney, where I have full working rights on a 485 visa. Somewhere the data is genuinely messy, and someone is waiting on a decision at the other end of it.
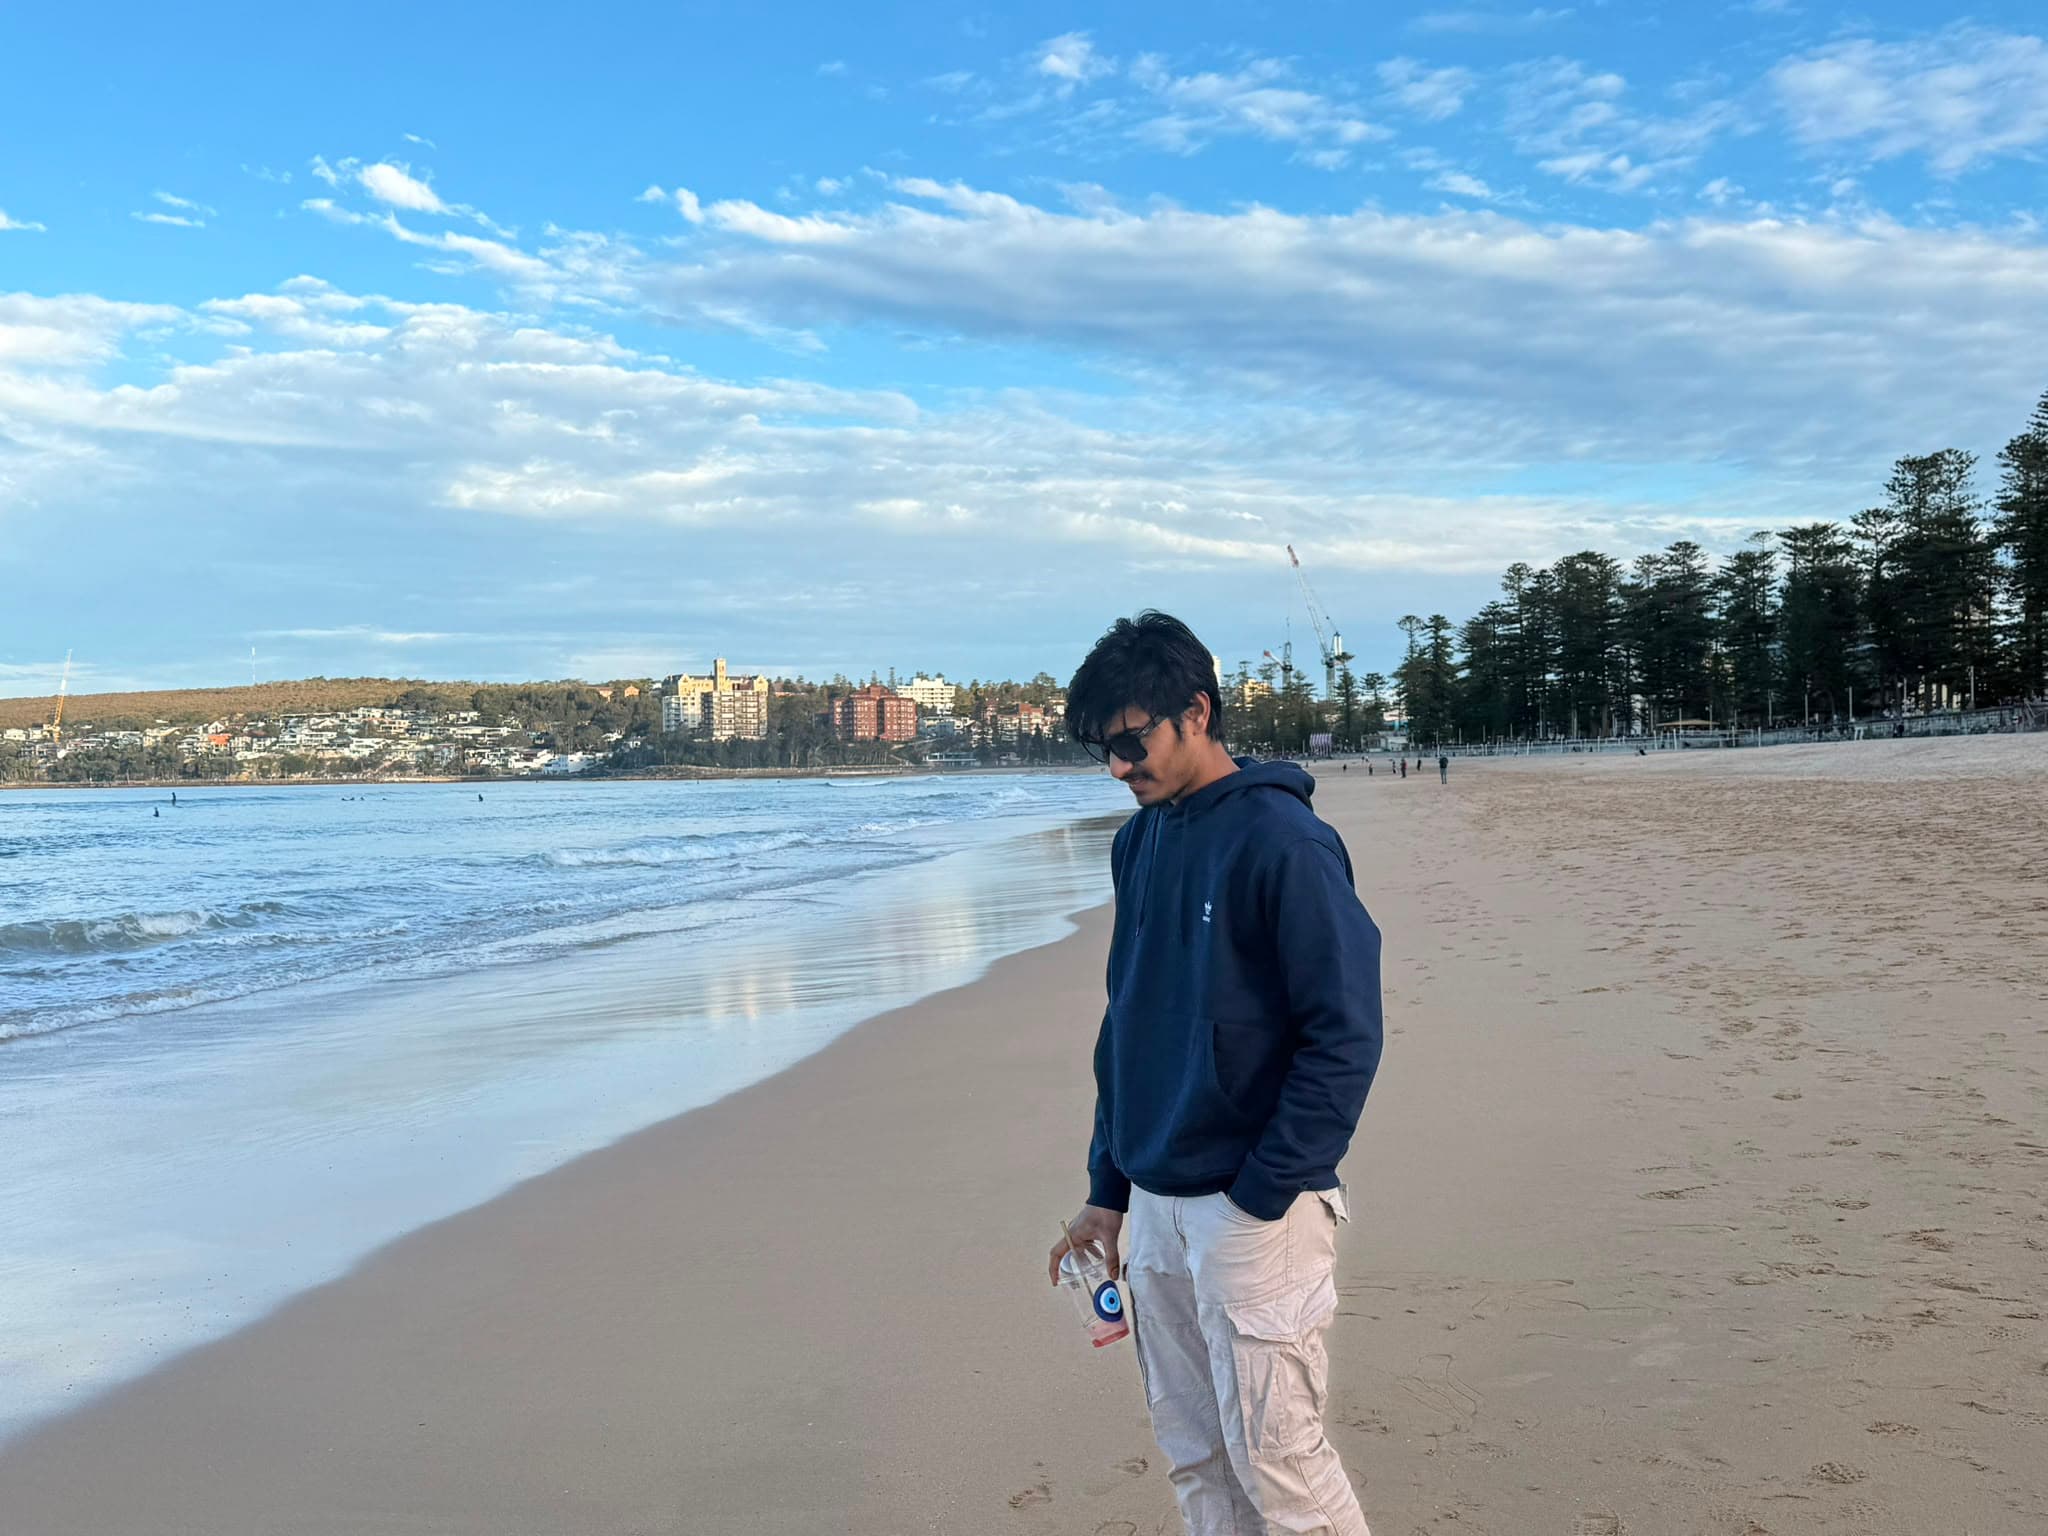
Sydney is where the Master’s happened, and where I want to put it to work.
Manly Beach · NSW
What I actually build with.
CoreWorking
- 01Languages
- Python
- SQL
- R
- 02Databases
- PostgreSQL
- 03Data & Analytics
- pandas
- ETL
- Data cleaning & validation
- Data modelling
- NumPy
- Statistical analysis
- Exploratory data analysis
- Churn analysis
- Customer segmentation
- SQLAlchemy
- psycopg2
- 04BI & Visualisation
- Tableau
- Power BI
- DAX
- matplotlib
- 05Machine Learning
- scikit-learn
- XGBoost
- SHAP
- TensorFlow / Keras
- OpenCV
- PyVista
- Trimesh
- 06Tools & Cloud
- Git
- Jupyter
- Jira
- Excel
- AWS (fundamentals)
The formal part.
Master of Data Science
2024 – 2026
Macquarie UniversitySydney, Australia · WAM 75.7
B.Tech, Computer Science & Engineering
2020 – 2024
GITAM UniversityIndia · CGPA 8.75 / 10
IBM Data Science Professional Certificate
Certificate
Coursera
Google Data Analytics Professional Certificate
Certificate
Coursera
AWS Cloud Virtual Internship
2023
AICTE / EduSkills
Want to see how I apply this?Four systems, built end to end.
Every project below runs the length of the pipeline, from schema design through to the dashboard someone actually reads.
Open to opportunitiesSydney, Australia